About me
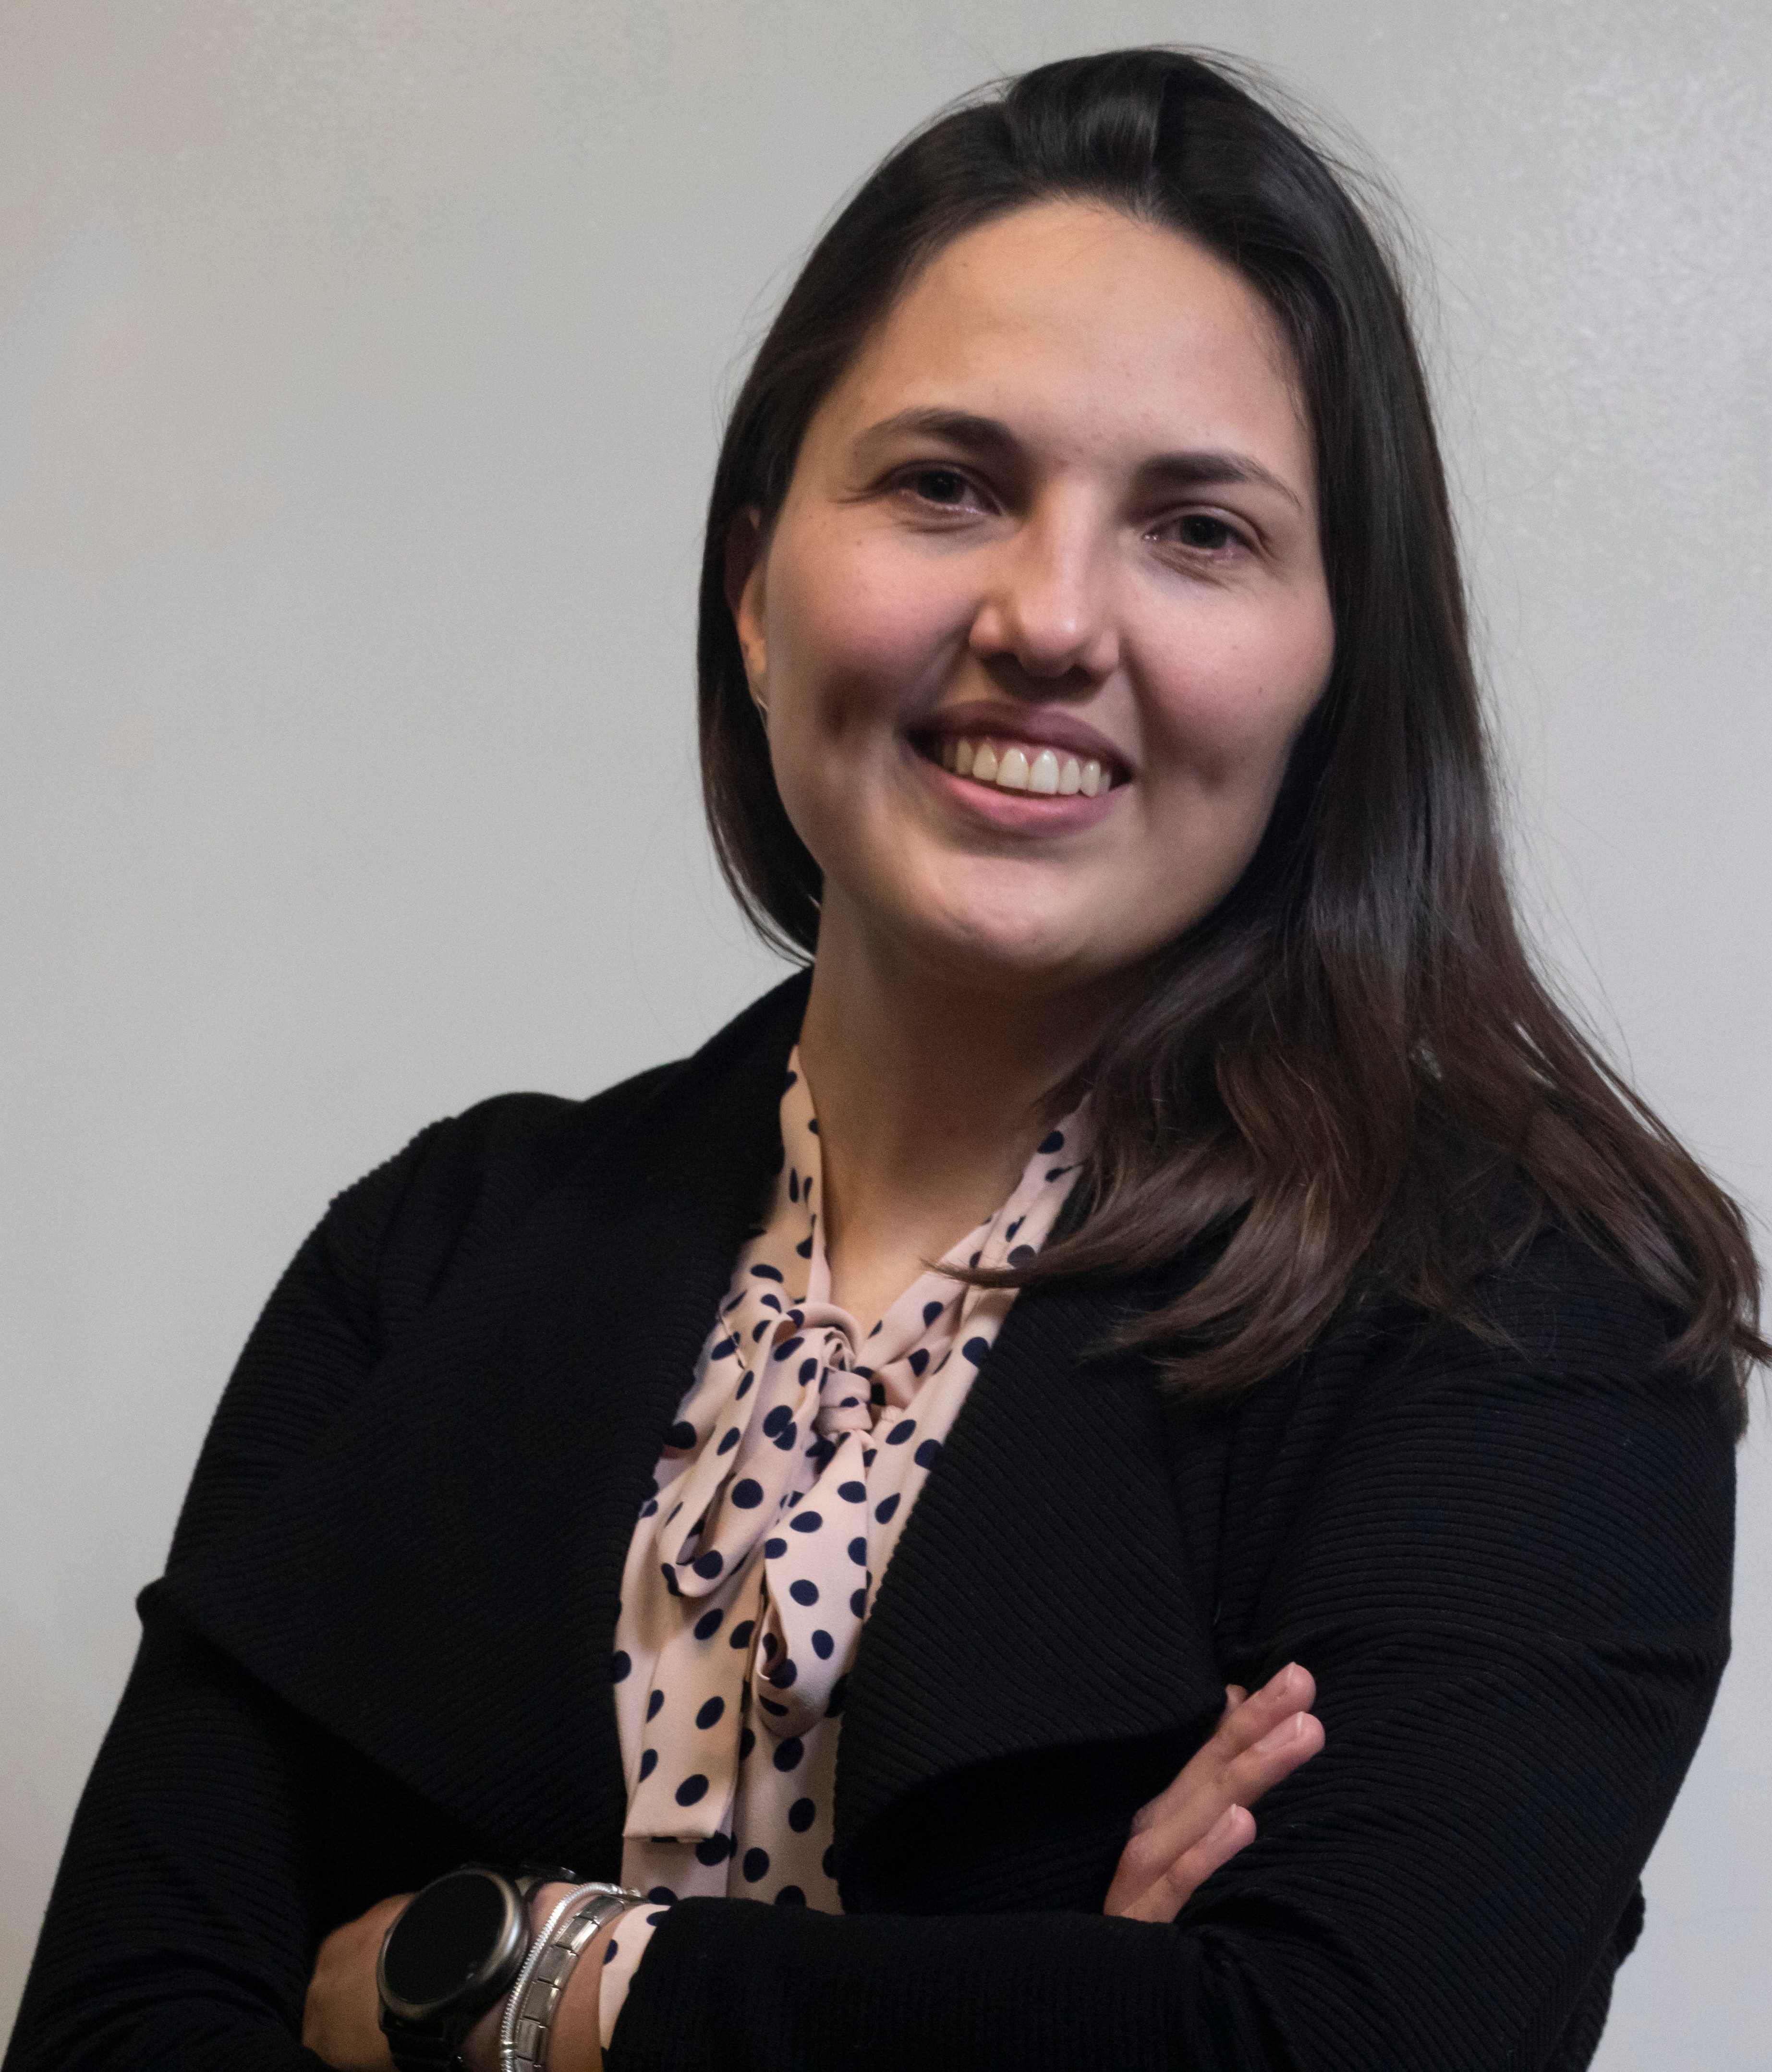
Hi there! My name is Ellie Kuznetsova. In media and publications, you’ll mostly see my legal name, Elizaveta Kuznetsova [yeh-lee-zah-VYEH-tah kooz-NYET-soh-vah], but in casual contexts, people usually refer to me as “Ellie”. As a rule of thumb, when in doubt (and we’re not talking legal documents), use Ellie — you can’t go wrong with that.I hold an MS in Computational Social Science from UC San Diego, where I combined my interests in linguistics, data, and language models. Before that, I earned an MA in Applied Linguistics and Teaching English as a Second Language from the English Department at Northern Arizona University. During my MA, I did research in corpus linguistics, educational technology, and writing studies, focusing on instructor feedback in English composition: higher- and lower-order concerns in instructor comments and rapport building between students and instructors. I received my BA in Linguistics from the Department of Foreign Languages at Pushkin Leningrad State University, where my program focused on interpretation and translation studies.
My research sits at the intersection of bilingualism and natural language processing, with a focus on code-switching and on building language technologies for multilingual communities. Current projects include developing code-switched minimal pairs for evaluating large language models and a sentence-embedding analysis of a Spanish–English tangram corpus. Previously, I contributed to the Writing Feedback Corpus (WFC), a corpus of instructor feedback on student writing.
You can reach me at ye dot s dot kuznetsova at gmail dot com. Some of my work can also be found on my GitHub.